
 Worksheets
Introduction to Parallel Programming
Total questions: 11
Worksheet time: 6mins
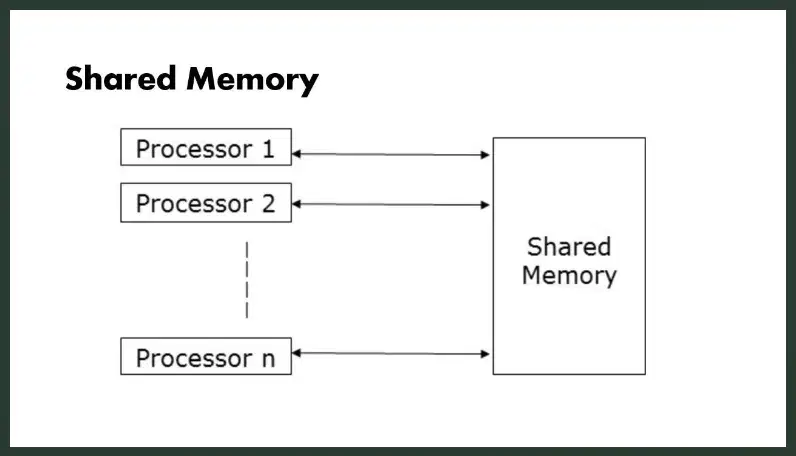
Which statement best describes the shared-memory model in parallel programming shown in the diagram?
Tasks execute on separate machines over a network link
Processors run sequentially on a single core and cache data
Multiple processors access one common memory space directly
Each processor uses its private memory with message passing
Which scenario best illustrates data parallelism in computing?
Stages of a workflow forming a processing pipeline
Different tasks executed by separate threads
Single processor sharing one memory space
Same operation applied to many data elements
Look at the client–server diagram in distributed systems. Which statement best describes how nodes interact in this setup?
Clients and servers run on one computer without networking
Servers send data only through local shared memory
Clients share a single memory with all servers
Independent nodes exchange requests using message passing
Which statement best describes the Client–Server model shown in the image?
Servers initiate requests and clients send responses
Multiple computers merge into one system for workloads
Clients initiate requests and servers send responses
Peers equally share tasks without central control
Which statement best describes the MapReduce framework shown in the diagrams?
A database engine for structured SQL queries only
A web server architecture for hosting static pages
A single-computer tool for local file backups
A model for parallel data processing across clusters
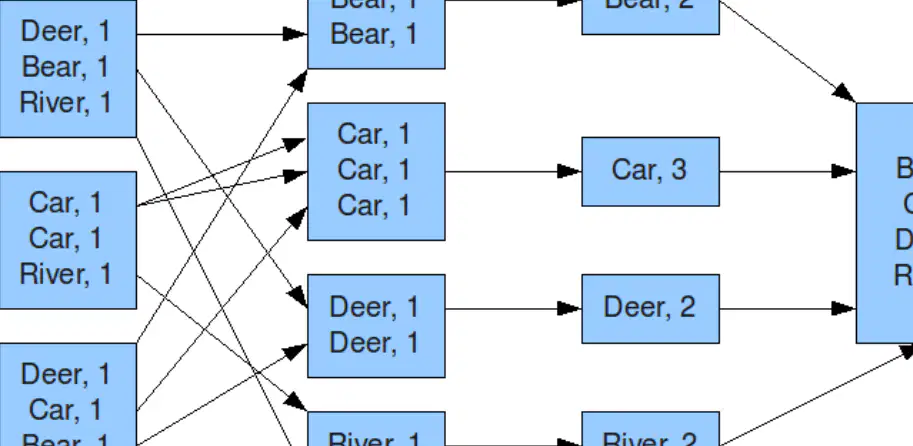
In the word count pipeline, what happens during the Shuffle and Sort phase?
Key–value pairs are grouped by keys before reducing
Input text is split into equal-sized chunks
Aggregated totals are calculated per unique key
Raw files are uploaded to cloud storage nodes
Given the stages Map, Shuffle & Sort, and Reduce, which task belongs to the Map phase in a word count job?
Emitting word,1 for each token encountered
Combining all partial sums per word
Distributing grouped keys to reducers
Rendering UI charts for final results
Which MapReduce phase groups intermediate values by key before sending them to reducers?
Map phase processes input chunks
Data locality places tasks near data
Reduce phase summarizes results
Shuffle and sort organizes by key
A research team runs an algorithm that must repeat dozens of times on the same dataset. Which platform best minimizes overhead for these iterations?
Twister iterative MapReduce
Manual reloading each iteration
Traditional single-pass Hadoop batch
Scaling by adding servers
Which feature of Twister reduces repeated disk reads during iterative processing by keeping static data available across worker nodes?
Long-running tasks keep mappers alive across iterations
Pub/sub messaging sends data through broker networks
Combine step aggregates reduce outputs before looping
In-memory caching loads static data once into memory
A machine learning job runs PageRank until ranks stop changing. Which concept explains why the graph structure is loaded once while current ranks update each round?
Loop control manages while loops between phases
YARN schedules containers across cluster nodes
Static versus variable data separates fixed from changing
Pub/sub messaging accelerates task communication

